


Document Management vs Content Management [2023 Guide] – Cloudwards
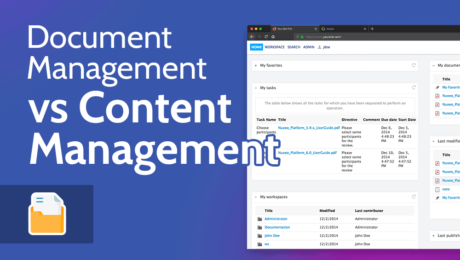
People often confuse document management vs content management systems. In this article, we’ll explore both DMS and CMS, what the similarities are and how their differences dictate which platform is the best for your business.
Document management and content management are closely related. On the surface, they appear to be the same thing, but when you begin to analyze document management vs content management, you begin to see the differences.
If your business is looking to implement a document management system (DMS) or a content management system (CMS), you may be left wondering which one is right for you.
The best document management software and content management systems can come with a hefty price tag, so it’s best to learn what you’re investing your money in and which platform will best serve your needs.
We’re here to help ease confusion and answer some common questions, which will put you in a better position to select which type of software you need to use.
Document management software is specifically designed to hold business documents that multiple users can organize, create, edit and access. A content management system applies to several content types like text, video and images, all of which are published publicly through a website.
Technically yes, you can use a CMS to create and store text-based documents. However, we wouldn’t advise using a CMS for document management as it doesn’t provide the same organization and creation tools as dedicated document management software.
Microsoft SharePoint is a document management system that also includes some traditional CMS features. For example, you can create private web pages and share content with other users in your business.
To help you learn more about document management systems and content management systems, we’re going to explore each platform separately, then look at some of the core differences and similarities.
A document management system is a piece of software that allows companies to manage documents throughout their business. See it as somewhat of a digital filing cabinet, where a range of documents exist and various users are able to access them.
However, unlike a physical filing cabinet, which is only capable of holding documents, an electronic document management system offers much more.
For example, certain document management software allows you to send out internal communications that help keep everyone up to date on critical business processes. You can also collaborate on documents, access older versions and allow multiple users to edit them.
The most common types of document management systems are on-premise and cloud-based. On-premise document management software gives you total control over your internal servers and allows you to establish security for your documents.
The cloud-based option means your documents exist on a third-party company’s servers. Cloud solutions make it easier to access documents on multiple devices, as well as collaborate on documents with others.
Among other things, good document management software enables you to create and store document types such as invoices, employee contracts, spreadsheets, training materials and almost any other business document you can imagine.
The very best also have tools that offer scanning capabilities so you can transfer paper documents to your electronic DMS. Scanning tools include optical character recognition, which lets you edit paper documents that you have migrated to electronic documents.
If you would like more information on what a DMS can do, check out our document management basics article. We also have a document management best practices guide, that outlines how to choose a DMS and make the most of its features.
A content management system is a space that allows you to upload various types of content such as text, images and video. Through various software options, a content management system lets you easily publish content publicly on the web without needing to know how to code it from scratch.
Whether you’re a blogger or a large online publication, you’ll need a content management system in order to create, schedule and publish content. A leading CMS, like WordPress, also offers templates for your website, and gives you the ability to create a unique design.
Most content management systems let you add multiple users to one centralized content stream. You can give users permission to create, edit and publish content. Other users, such as editors, can also access content and edit where appropriate.
After your website goes live, you can access your content management system and create new web pages within your website. You can also modify content even after you publish it online, and all of this can be done without the need for a web developer. This makes it simple for even inexperienced CMS users.
Now that you have a better understanding of what a DMS and a CMS are, let’s take a closer look at some of the core differences and similarities.
A DMS tends to handle what’s called structured data; it’s a space that allows you to easily categorize, search and share data within one centralized platform.
By contrast, a CMS is a place for unstructured data, where content does not have a defined data model and isn’t organized in a defined manner.
Structured data includes easily searchable data, such as names, addresses, charts, documents and PDF files; whereas unstructured data involves data that’s not easy to search, for example video files and audio files.
The platforms share similarities in that they offer a centralized space to upload, create, retrieve and share content. That’s really where the common ground ends, as the type of content created and shared is vastly different.
By now, you should be able to ascertain which platform is the best for your business. If you’re still unsure, here are some things to consider.
Two other terms you’re likely to come across are enterprise content management (ECM) and enterprise document management (EDM). Despite the different terms, not much separates an enterprise content management system from a standard CMS, and the same is true with a DMS. The main difference is scalability.
ECM software allows you to add and manage more users, while also giving them the ability to access content and documents from multiple devices in different locations.
Due to the size of each platform, it’s common to see more tools for automation that allow you to provide fluid updates on business processes and content. This makes enterprise-level management systems ideal for large businesses.
While the foundations of a DMS and CMS are similar, you can clearly see that each software type is built for different purposes. Both of them will certainly help you manage content and work with others on different content and document types; a defined objective will help choose which platform you need.
Which DMS do you use? What’s your favorite CMS? Do you utilize enterprise content management? How do you keep track of your business’ digital assets? Is there something you wish we explained in the article? Let us know in the comments. Thanks for reading.
document.getElementById( “ak_js_1” ).setAttribute( “value”, ( new Date() ).getTime() );
Also interesting
Most popular on Cloudwards
© 2007-2023 Cloudwards.net – We are a professional review site that receives compensation from the companies whose products we review. We test each product thoroughly and give high marks to only the very best. We are independently owned and the opinions expressed here are our own.
Because the Cloudwards.net team is committed to delivering accurate content, we implemented an additional fact-checking step to our editorial process. Each article that we fact check is analyzed for inaccuracies so that the published content is as accurate as possible.
You can tell that an article is fact checked with the Facts checked by symbol, and you can also see which Cloudwards.net team member personally verified the facts within the article. However, providers frequently change aspects of their services, so if you see an inaccuracy in a fact-checked article, please email us at feedback[at]cloudwards[dot]net. We strive to eventually have every article on the site fact checked. Thank you.
- Published in Uncategorized
DynamoDB Data Transformation Safety: from Manual Toil to … – InfoQ.com
Live Webinar and Q&A: Panel: 2023 Data Engineering Trends and Predictions (January 19, 2023) Save Your Seat
Facilitating the Spread of Knowledge and Innovation in Professional Software Development
2022 was another year of significant technological innovations and trends in the software industry and communities. The InfoQ podcast co-hosts met last month to discuss the major trends from 2022, and what to watch in 2023.. This article is a summary of the 2022 software trends podcast.
Anna Shipman discusses her experience joining the FT to lead on FT.com a few years after launchm and shares things implemented to stop the drift towards an unmaintainable system and another rebuild.
Sara Bergman introduces the field of green software engineering, showing options to estimate the carbon footprint and discussing ideas on how to make Machine Learning greener.
In this podcast Shane Hastie spoke to Melissa Daley, Bob Crews and Adam Sandman, about the state of testing and how to instil a culture of quality into software teams
GitHub Actions is an effective CI tool. However, integrating it into enterprise organizations can be challenging. This article looks at best practices for GitHub Actions in the enterprise.
Learn how to achieve high-level observability without picking and choosing which logs to collect. Register Now.
Adopt the right emerging trends to solve your complex engineering challenges. Register Now.
Your monthly guide to all the topics, technologies and techniques that every professional needs to know about. Subscribe for free.
InfoQ Homepage Articles DynamoDB Data Transformation Safety: from Manual Toil to Automated and Open Source
Nov 23, 2022 15 min read
by
reviewed by
When designing a product to be a self-serve developer tool, there are often constraints – but likely one of the most common ones is scale. Ensuring our product, Jit – a security-as-code SaaS platform, was built for scale was not something we could embed as an afterthought, it needed to be designed and handled from the very first line of code.
We wanted to focus on developing our application and its user experience, without having challenges with issues and scale be a constant struggle for our engineers. After researching the infrastructure that would enable this for our team – we decided to use AWS with a serverless-based architecture.
AWS Lambda is becoming an ever-popular choice for fast-growing SaaS systems, as it provides a lot of benefits for scale and performance out of the box through its suite of tools, and namely the database that supports these systems, AWS’s DynamoDB.
Presented by: Dunith Dhanushka – Senior Developer Advocate, Redpanda Data
Save your seat
One of its key benefits is that it is already part of the AWS ecosystem, and therefore this abstracts many of the operational tasks of management and maintenance, such as maintaining connections with the database, and it requires minimal setup to get started in AWS environments.
As a fast-growing SaaS operation, we need to evolve quickly based on user and customer feedback and embed this within our product. Many of these changes in application design have a direct impact on data structures and schemas.
With rapid and oftentimes significant changes in the application design and architecture, we found ourselves needing to make data transformations in DynamoDB very often, and of course, with existing users, it was a priority that this be achieved with zero downtime. (In the context of this article Data Transformation will refer to modifying data from state A to state B).
In the spirit of Brendon Moreno from the UFC:
Maybe not today, maybe not tomorrow, and maybe not next month, but only one thing is true, you will need to make data transformations one day, I promise.
Yet, while data transformation is a known constant in engineering and data engineering, it remains a pain point and challenge to do seamlessly. Currently, in DynamoDB, there is no easy way to do it programmatically in a managed way, surprisingly enough.
While there are many forms of data transformation, from replacing an existing item’s primary key to adding/removing attributes, updating existing indexes – and the list goes on (these types are just a few examples), there remains no simple way to perform any of these in a managed and reproducible manner, without just using breakable or one-off scripting.
Below, we are going to dive into a real-world example of a data transformation process with production data.
Let’s take the example of splitting a “full name” field into its components “first name” and “last name”. As you can see in the example below, the data aggregation currently writes names in the table with a “full name” attribute. But let’s say we want to transform from a full name, and split this field into first and last name fields.
BeforeIdFullName123Guy Br
AfterIdFirstNameLastName123GuyBr
Looks easy, right? Not so, to achieve just this simple change these are the steps that will need to be performed on the business logic side, in order to successfully transform this data.
But let's discuss some of the issues you would need to take into account before you even get started, such as – how do you run and manage these transformations in different application environments? Particularly when it’s not really considered a security best practice to have access to each environment. In addition, you need to think about service dependencies. For example, what should you do when you have another service dependent on this specific data format? Your service needs to be backward compatible and still provide the same interface to external services relying on it.
When you have production clients, possibly one of the most critical questions you need to ask yourself before you modify one line of code is how do you ensure that zero downtime will be maintained?
Some of the things you’d need to plan for to avoid any downtime is around testing and verification. How do you even test your data transformation script? What are some good practices for running a reliable dry run of a data transformation on production data?
There are so many things to consider before transforming data.
Now think that this is usually, for the most part, done manually. What an error-prone, tedious process! It looks like we need a fine-grained process that will prevent mistakes and help us to manage all of these steps.
To avoid this, we understood we’d need to define a process that would help us tackle the challenges above.
Figure 1: Rewrite Process Flow Chart
First, we started by adjusting the backend code to write the new data format to the database while still keeping the old format, by first writing the FullName, FirstName and LastName to provide us some reassurance of backward compatibility. This would enable us to have the ability to revert to the previous format if something goes terribly wrong.
Link to GitHub
Next, we wrote a data transformation script that scans the old records and appends the FirstName and LastName attributes to each of them, see the example below:
Link to GitHub
After writing the actual script (which is the easy part), we now needed to verify that it actually does what it’s supposed to. To do so, the next step was to run this script on a test environment and make sure it works as expected. Only after the scripts usability is confirmed, it could be run on the application environments.
The last phase is the cleanup, this includes taking the plunge and ultimately deleting the FullName column entirely from our database attributes. This is done in order to purge the old data format which is not used anymore, and reduce clutter and any future misuse of the data format.
Link to GitHub
Lets quickly recap what we have done in the process:
This well-defined process helped us to build much-needed safety and guardrails into our data transformation process. As we mentioned before, with this process we were able to avoid downtime by keeping the old format of the records until we don’t need them anymore. This provided us with a good basis and framework for more complex data transformations.
Now that we have a process––let’s be honest, real-world data transformations are hardly so simple. Let’s assume, a more likely scenario, that the data is actually ingested from an external resource, such as the GitHub API, and that our more advanced data transformation scenario actually requires us to ingest data from multiple sources.
Let’s take a look at the example below for how this could work.
In the following table, the GSI partition key is by GithubUserId.
For the sake of this data transformation example, we want to add a “GithubUsername” column to our existing table.
BeforeIdGithubUserId1237654321
AfterIdGithubUserIdGithubUsername1237654321Guy7B
This data transformation looks seemingly as straightforward as the example with the full name, but there is a little twist.
How can we get the Github username if we don’t have this information? We have to use an external resource, in this case, it's the Github API.
GitHub has a simple API for extracting this data (you can read the documentation here). We will pass the GithubUserId and get information about the user which contains the Username field that we want.https://api.github.com/user/:id
The naive flow is similar to the full name example above:
However, in contrast to our previous flow, there is an issue with this naive flow. The flow above is not safe enough. What happens if you have issues while running the data transformation when calling the external resource? Perhaps the external resource will crash / be blocked by your IP or is simply unavailable for any other reason? In this case, you might end up with production errors or a partial transformation, or other issues with your production data.
What can we do on our end to make this process safer?
While you can always resume the script if an error occurs or try to handle errors in the script itself, however, it is important to have the ability to perform a dry run with the prepared data from the external resource before running the script on production. A good way to provide greater safety measures is by preparing the data in advance.
Below is the design of the safer flow:
Only after we do this, we scan the user records, get GithubUsername for each of them using Github API, append it to a JSON Object `{ [GithubUserId]: GithubUsername }` and then write that JSON to a file.
This is what such a flow would look like:
Link to GitHub
Next we scan the user records (get GithubUsername by GithubUserId for each record using Preparation Data), and move ahead to updating the record.
Link to GitHub
And finally, like the previous process, we wrap up by running the script on the testing environment, and then the application environments.
Once we built a robust process that we could trust for data transformation, we understood that to do away with human toil and ultimately error, the best bet would be to automate it.
We realized that even if this works for us today at our smaller scale, manual processes will not grow with us. This isn’t a practical long-term solution and would eventually break as our organization scales. That is why we decided to build a tool that would help us automate and simplify this process so that data transformation would no longer be a scary and painful process in the growth and evolution of our product.
Every data transformation is just a piece of code that helps us to perform a specific change in our database, but these scripts, eventually, must be found in your codebase.
This enables us to do a few important operations:
By enabling automation for data transformation processes, you essentially make it possible for every developer to be a data transformer. While you likely should not give production access to every developer in your organization, applying changes is the last mile. When only a handful of people have access to production, this leaves them with validating the scripts and running them on production, and not having to do all of the heavy lifting of writing the scripts too. We understand it consumes more time than needed for those operations and it is not safe.
When the scripts in your codebase and their execution are automated via CI/CD pipelines
other developers can review them, and basically, anyone can perform data transformations on all environments, alleviating bottlenecks.
Now that we understand the importance of having the scripts managed in our codebase, we want to create the best experience for every data-transforming developer.
Every developer prefers to focus on their business logic – with very few context disruptions and changes. This tool can assist in keeping them focused on their business logic, and not have to start from scratch every time they need to perform data transformations to support their current tasks.
For example – dynamo-data-transform provides the benefits of:
Quick Installation for serverless:
The package can be used as a standalone npm package see here.
To get started with DynamoDT, first run:npm install dynamo-data-transform --save-dev
To install the package through NPM (you can also install it via…)
Next, add the tool to your serverless.yml Run:npx sls plugin install -n dynamo-data-transform
You also have the option of adding it manually to your serverless.yml:plugins: - dynamo-data-transform
You can also run the command:sls dynamodt --help
To see all of the capabilities that DynamoDT supports.
Let’s get started with running an example with DynamoDT. We’ll start by selecting an example from the code samples in the repo, for the sake of this example, we’re going to use the example `v3_insert_users.js`, however, you are welcome to test it out using the examples you’ll find here.
We’ll initialize the data transformation folder with the relevant tables by running the command: npx sls dynamodt init --stage local
For serverless (it generates the folders using the resources section in the serverless.yml):
The section above should be in serverless.yml
The data-transformations folder generated with a template script that can be found here.
We will start by replacing the code in the template file v1_script-name.js with:
Link to GitHub
For most of the regular data transformations, you can use the util functions from the dynamo-data-transform package. This means you don’t need to manage the versions of the data transformation scripts, the package will do this work for you. Once you’ve customized the data you’ll want to transform, you can test the script using the dry run option by running:npx sls dynamodt up --stage local --dry
The dry run option prints the records in your console so you can immediately see the results of the script, and ensure there is no data breakage or any other issues.
Once you’re happy with the test results, you can remove the –dry flag and run it again, this time it will run the script on your production data, so make sure to validate the results and outcome.
Once you have created your data transformation files, the next logical thing you’d likely want to do is add this to your CI/CD. To do so add the command to your workflow/ci file for production environments.
The command will run immediately after the `sls deploy` command, which is useful for serverless applications.
Finally, all of this is saved, as noted above so if you want to see the history of the data transformations, you can run:
`npx sls dynamodt history –table UserExample –stage local`
The tool also provides an interactive CLI for those who prefer to do it this way.
And all of the commands above are supported via CLI as well.
With Dynamo Data Transform, you get the added benefits of being able to version and order your data transformation operations and manage them in a single place. You also have the history of your data transformation operations if you would like to roll back an operation. And last but not least, you can reuse and review your previous data transformations.
We have open-sourced the Dynamo Data Transform tool that we built for internal use to perform data transformations on DynamoDB and serverless-based environments and manage these formerly manual processes in a safe way.
The tool can be used as a Serverless Plugin and as a standalone NPM package.
Feel free to provide feedback and contribute to the project if you find it useful.
Figure 2: Data Transformation Flow Chart
Becoming an editor for InfoQ was one of the best decisions of my career. It has challenged me and helped me grow in so many ways. We’d love to have more people join our team.
A round-up of last week’s content on InfoQ sent out every Tuesday. Join a community of over 250,000 senior developers. View an example
We protect your privacy.
You need to Register an InfoQ account or Login or login to post comments. But there’s so much more behind being registered.
Get the most out of the InfoQ experience.
Allowed html: a,b,br,blockquote,i,li,pre,u,ul,p
by Rob Finneran,
by Rob Finneran,
Your message is awaiting moderation. Thank you for participating in the discussion.
Great article on an often-overlooked topic! I am always looking for more tools and more ideas about DynamoDB since it is such an important part of my AWS tool set. Here are a couple of related ideas that I have been thinking about: (1) Schema control or versioning of the JSON structure of the DynamoDB rows, and (2) data versioning and related topics like optimistic concurrency, and (3) AWS Glue crawlers and related mechanisms that allow joining DynamoDB “tables” with other data sources in a SQL JOIN command. Also, check out tools like Dynobase and let us all know of your other finds!
Allowed html: a,b,br,blockquote,i,li,pre,u,ul,p
Allowed html: a,b,br,blockquote,i,li,pre,u,ul,p
A round-up of last week’s content on InfoQ sent out every Tuesday. Join a community of over 250,000 senior developers. View an example
We protect your privacy.
Real-world technical talks. No product pitches.
Practical ideas to inspire you and your team.
March 27-29, 2023. Attend in-person or online.
QCon London brings together the world’s most innovative senior software engineers across multiple domains to share their real-world implementation of emerging trends and practices.
Level-up on 15 major software and leadership topics including Modern Frontend Development and Architecture, Enhancing Developer Productivity and Experience, Remote and Hybrid Work, Debugging Production, AI/ML Trends, Data Engineering Innovations, Architecture in 2025, and more.
SAVE YOUR SPOT NOW
InfoQ.com and all content copyright © 2006-2023 C4Media Inc.
Privacy Notice, Terms And Conditions, Cookie Policy
- Published in Uncategorized
Appfire Expands into the Microsoft Ecosystem with Acquisition of … – Business Wire

7pace Timetracker is the industry’s first AI-driven multi-cloud time management solution and is a leading integration for teams using Azure DevOps and GitHub. Expansion to the Atlassian ecosystem is planned.
BOSTON–(BUSINESS WIRE)–Appfire, an enterprise collaboration software company that enables teams to plan and deliver their best work, announced today the acquisition of German company 7pace, creators of the top-selling app for Azure DevOps, 7pace Timetracker, which recently launched on GitHub. This acquisition marks a strategic expansion for Appfire into the Microsoft ecosystem, with continued staffing, product expansion, and go-to-market investments planned for both Azure DevOps and GitHub products. In addition, Appfire and 7pace will bring this leading solution to the Atlassian ecosystem, enhancing and expanding time management offerings for customers.
This latest addition to Appfire’s purpose-built portfolio is driven by a mission to equip and connect every team so they can plan and deliver their best work. Designed and built by developers for developers, 7pace Timetracker incorporates AI and machine learning to seamlessly capture time data within the developer’s workflow. This technology gives individuals and teams the real-time insights they need to improve the way they work across multiple platforms.
“At Appfire, we follow teams, not tools,” comments Randall Ward, Co-Founder and CEO of Appfire. “To drive success and ambitious transformation, product developers need to spend more time innovating. 7pace has developed an AI-driven experience that teams not only need, but want, and we’re thrilled to welcome Marc Schaeffler and the 7pace team to Appfire.”
Time tracking is often perceived as a necessary but high-friction activity in development environments, with negative perceptions of managerial surveillance, lost productivity, and unintuitive platforms. Timetracker was built to not only relieve these pain points, but to actively shift the culture associated with time tracking to address the needs of the developer. The product identifies individual patterns and uses underlying work item data to guide developers, flipping the script on an outdated, contextually unaware time entry model.
Capturing and aggregating time data across platforms helps work flow across tools and teams, aligning perfectly with Appfire’s product strategy.
“This acquisition represents a continued investment in our customers and an opportunity to disrupt the legacy time management market,” comments 7pace Founder and CEO Marc Schaeffler. “We have searched for a partner that aligns with our values, not only internally with our people, but on the level of service and respect we show our customers, and we immediately felt at home with Appfire.”
The entire 7pace team — many of whom are local to 7pace’s headquarters of Munich, Germany — has joined Appfire. This new location will allow Appfire to more directly support customers and channel partners within the German market.
About Appfire
Appfire is a leading enterprise collaboration software provider for teams looking to make work flow, from planning to product ideation, to product development, project delivery, and beyond. Appfire gives teams the best solutions to enhance, augment, connect, and extend platforms like Atlassian, Salesforce, and Microsoft. Appfire enables teams to thrive and do their best work. Many of Appfire’s popular software products are sold on the Atlassian Marketplace, where Appfire has the most widely adopted portfolio of Atlassian apps with 200,000+ active installations across tens of thousands of customers worldwide. Appfire’s popular solutions help teams with Workflow & Automation, Product Portfolio Management, IT Service Management, Document Management, Business Intelligence and Reporting, Administrative Tools, Agile Tools, Developer Tools, Time Tracking, Publishing, and Visual Collaboration. Learn more at www.appfire.com.
About 7pace
7pace Timetracker is a fully built-in professional time management solution for teams using Azure DevOps and GitHub (beta). 7pace Timetracker supports engineers, builds feedback, and helps teams learn and improve over time. It automates standard tasks, allows teams to create reports, and helps forecast project time. From user stories to individual work items or issues, 7pace Timetracker integrates seamlessly into existing IT landscapes. 7pace offers a desktop app, an integrated API, and more options to get project and time data wherever it’s needed. Learn more at www.7pace.com.
Josh Payne, PR Director
joshua.payne@walkersands.com
781-264-8096
Josh Payne, PR Director
joshua.payne@walkersands.com
781-264-8096
- Published in Uncategorized
Case Management Software Market is foreseen to grow at CAGR of … – Digital Journal
Hi, what are you looking for?
By
Published
Case management software is a type of software used to manage cases in a court or other legal setting. It is used to track the progress of a case from start to finish, store associated documents and evidence, and provide access to the case data to all parties involved. The software typically includes features such as task management, calendar management, document management, and collaborative communication tools. It is designed to help legal professionals save time and money, and improve the overall efficiency of their workflow.
Case Management Software Market research is an intelligence report with meticulous efforts undertaken to study the right and valuable information. The data which has been looked upon is done considering both, the existing top players and the upcoming competitors. Business strategies of the key players and the new entering market industries are studied in detail. Well explained SWOT analysis, revenue share and contact information are shared in this report analysis.
The global Case Management Software market is expected to grow at a CAGR of 9% in terms of revenue over the forecast period from 2023 to 2030, owing to a number of variables about which A2Z Market Research provides detailed insights and projections in the global Case Management Software market research.
Get the PDF Sample Copy (Including FULL TOC, Graphs and Tables) of this report @:
https://a2zmarketresearch.com/sample-request
Top Key Players Profiled in this report are:
Pegasystems, IBM, LegalEdge, AINS, Salesforce, MyCase, Actionstep, Dell Technologies, Appian, Athena Software
The key questions answered in this report:
Global Case Management Software Market Segmentation:
Market Segmentation: By Type
Web-Based
Cloud Based
On-Premise
Market Segmentation: By Application
Law Firms
Hospitals
Various factors are responsible for the market’s growth trajectory, which are studied at length in the report. In addition, the report lists down the restraints that are posing threat to the global Case Management Software market. It also gauges the bargaining power of suppliers and buyers, threat from new entrants and product substitute, and the degree of competition prevailing in the market. The influence of the latest government guidelines is also analyzed in detail in the report. It studies the Case Management Software market’s trajectory between forecast periods.
Regions Covered in the Global Case Management Software Market Report 2022:
The Middle East and Africa (GCC Countries and Egypt)
North America (the United States, Mexico, and Canada)
South America (Brazil etc.)
Europe (Turkey, Germany, Russia UK, Italy, France, etc.)
Asia-Pacific (Vietnam, China, Malaysia, Japan, Philippines, Korea, Thailand, India, Indonesia, and Australia
The cost analysis of the Global Case Management Software Market has been performed while keeping in view manufacturing expenses, labor cost, and raw materials and their market concentration rate, suppliers, and price trend. Other factors such as Supply chain, downstream buyers, and sourcing strategy have been assessed to provide a complete and in-depth view of the market. Buyers of the report will also be exposed to a study on market positioning with factors such as target client, brand strategy, and price strategy taken into consideration.
For Any Query or Customization:
https://a2zmarketresearch.com/ask-for-customization
The report provides insights on the following pointers:
Market Penetration: Comprehensive information on the product portfolios of the top players in the Case Management Software market.
Product Development/Innovation: Detailed insights on the upcoming technologies, R&D activities, and product launches in the market.
Competitive Assessment: In-depth assessment of the market strategies, geographic and business segments of the leading players in the market.
Market Development: Comprehensive information about emerging markets. This report analyzes the market for various segments across geographies.
Market Diversification: Exhaustive information about new products, untapped geographies, recent developments, and investments in the Case Management Software market.
Table of Contents
Global Case Management Software Market Research Report 2022 – 2029
Chapter 1 Case Management Software Market Overview
Chapter 2 Global Economic Impact on Industry
Chapter 3 Global Market Competition by Manufacturers
Chapter 4 Global Production, Revenue (Value) by Region
Chapter 5 Global Supply (Production), Consumption, Export, Import by Regions
Chapter 6 Global Production, Revenue (Value), Price Trend by Type
Chapter 7 Global Market Analysis by Application
Chapter 8 Manufacturing Cost Analysis
Chapter 9 Industrial Chain, Sourcing Strategy and Downstream Buyers
Chapter 10 Marketing Strategy Analysis, Distributors/Traders
Chapter 11 Market Effect Factors Analysis
Chapter 12 Global Case Management Software Market Forecast
Buy Exclusive Report @:
https://a2zmarketresearch.com/checkout
If you have any special requirements, please let us know and we will offer you the report as you want.
About A2Z Market Research:
The A2Z Market Research library provides syndication reports from market researchers around the world. Ready-to-buy syndication Market research studies will help you find the most relevant business intelligence.
Our Research Analyst Provides business insights and market research reports for large and small businesses.
The company helps clients build business policies and grow in that market area. A2Z Market Research is not only interested in industry reports dealing with telecommunications, healthcare, pharmaceuticals, financial services, energy, technology, real estate, logistics, F & B, media, etc. but also your company data, country profiles, trends, information and analysis on the sector of your interest.
Contact Us:
Roger Smith
1887 WHITNEY MESA DR HENDERSON, NV 89014
[email protected]
+1 775 237 4157
COMTEX_422461836/2769/2023-01-11T01:53:21
Drones deployed on a scale never seen before to carry out surveillance and strikes have become a defining feature of the conflicts.
The hottest startup in Silicon Valley right now is OpenAI, the Microsoft-backed developer of ChatGPT.
Tesla announced it will cut the price of its best-selling electric vehicle models up to 20 percent in Europe and the United States.
JPMorgan Chase reported higher fourth-quarter profits Friday, boosted by income tied to increasing interest rates.
COPYRIGHT © 1998 – 2023 DIGITAL JOURNAL INC. Sitemaps: XML / News . Digital Journal is not responsible for the content of external sites. Read more about our external linking.
- Published in Uncategorized
American Financial Resources, Inc. Expands Partnership with … – Business Wire

Lender accelerates digital transformation, scales operations, and enhances the overall mortgage experience.
SANTA CLARA, Calif.–(BUSINESS WIRE)–Tavant, a Silicon Valley-based provider of industry-leading digital lending solutions, and American Financial Resources, Inc. (AFR), a national mortgage lender, operating in the wholesale, correspondent, and retail origination channels, have partnered to enhance the lender’s digital mortgage experience, end-to-end. Leveraging Tavant’s Touchless Lending™, AFR’s correspondent lenders, mortgage brokers, loan originators, and consumers will now be able to automate the traditionally cumbersome lending process, providing a more streamlined and seamless experience for all stakeholders.
Tavant’s Touchless Documents instantly recognizes documents, automating document classification, indexing, splitting, categorization/subcategorization, pairing with borrowers, and data extraction with the highest accuracy. Additionally, the Touchless Lending platform integrates seamlessly with existing lender systems, including CRMs, Point-of-Sales, LOS, and document management systems, to optimize document-related workflows, organize and process documents faster, and deposit the results of the document classification and data extraction back into the system of record.
“With the launch of FinDecision being so successful, adding Tavant’s Touchless Documents into the mix seemed like the logical next step,” said Scott Dubnoff, Chief Technology Officer at American Financial Resources, Inc. “And we were right. Their implementation was a smooth and painless process. It took about six weeks to integrate Tavant’s product into our systems fully. After one month of running Touchless Docs with real data, we determined their document classification accuracy greatly surpassed our expectations. We have only just started with this technology yet are already seeing returns in both labor efficiency and data accuracy. We have only scratched the surface with document classification and plan to expand to data extraction next. This opens even more possibilities for automation as we look to expand usage of the product to other areas of our process.”
Before deploying Touchless Documents, processing broker-submitted loan documents was time-consuming and labor-intensive, requiring the utilization of a pool of human resources and turnaround times that could potentially be overnight. After implementing Tavant’s Touchless Documents, what used to take hours now takes minutes. Brokers can get immediate feedback on their file uploads and provide direct input to their borrowers on requested document uploads. After only one month of usage, Touchless Docs has processed close to 500 loans and over 90k pages of loan documentation with a document classification success rate of approximately 92%.
“AFR and Tavant have aligned missions to make homeownership more accessible for all and to provide several offerings that can support underserved communities in the housing market,” said Hassan Rashid, Chief Revenue Officer at Tavant. “While lenders have had to undergo lengthy processes in the past manually, Tavant now introduces a machine-oriented approach that successfully increases workflow up to 80% by automating and regulating the processes of loan application and disbursal.”
As the leading Fintech software and solutions provider for more than 20 years, Tavant proactively anticipates customer needs and adjusts accordingly to provide the right configurable solutions. American Financial Resources joins Tavant’s growing customer base, which originates one out of every three loans in the United States. Tavant’s VΞLOX product suite, which now includes Touchless Lending™, maximizes data-driven decision-making to solve even the most complex lender and borrower challenges.
About Tavant
Headquartered in Santa Clara, Calif., Tavant is a digital products and solutions company that provides impactful results to its customers across North America, Europe, and Asia-Pacific. Founded in 2000, the company employs over 3000 people and is a recognized top employer. Tavant is creating an AI-powered intelligent lending enterprise by reimagining customer experiences, driving operational efficiencies, and improving collaboration.
Find Tavant on LinkedIn and Twitter.
About American Financial Resources, Inc.
American Financial Resources, Inc. (AFR) offers a comprehensive array of residential mortgage products to meet various financing needs. AFR is a leading FHA 203(k) lender for sponsored originations and an innovator in construction and renovation lending. AFR utilizes the latest technology and delivers educational resources to correspondent lenders, mortgage brokers, loan originators, and consumers. American Financial Resources, Inc. is an Equal Housing Lender and Equal Opportunity Employer. Lender NMLS 2826 at www.nmlsconsumeraccess.org. For more information, visit www.afrcorp.com.
Adrie Morales
adrie@williammills.com
678-781-7227
Adrie Morales
adrie@williammills.com
678-781-7227
- Published in Uncategorized
Right Networks Expands Intelligent Cloud with Addition of … – CPAPracticeAdvisor.com

Hello. It looks like you’re using an ad blocker that may prevent our website from working properly. To receive the best experience possible, please make sure any blockers are switched off and refresh the page.
If you have any questions or need help you can email us
Accounting & Audit
The alliance will enable accounting firms and professionals to easily access and securely share sensitive client documents directly within …
Dec. 06, 2022
Right Networks, the only intelligent accounting cloud, has announced a new partnership with SmartVault, a provider of document management and secure file sharing for the accounting profession. The alliance will enable accounting firms and professionals to easily access and securely share sensitive client documents directly within their fully managed cloud environments from Right Networks.
“For us, security is our number one priority, and having both SmartVault and Right Networks gives me peace of mind that my data and my clients’ data is secure and easily accessible in the cloud,” said Caleb Jenkins, EA, CQP, Leader of Client Accounting Services at RLJ Financial Services, Inc. “Right Networks enables us to run our more powerful desktop-based software applications in the cloud and acts as a data bridge and connector to other cloud applications. At the same time, SmartVault enables us to integrate with other apps, reducing security risks by preventing documents from being shared via email.”
Accountants Can Work More Securely and Efficiently in the Cloud with Right Networks and SmartVault
SmartVault can now be purchased directly from Right Networks as part of its intelligent accounting cloud, giving accounting firms and professionals the critical tools needed to operate in the cloud securely, easily and efficiently.
“SmartVault and Right Networks are both on a mission to deliver purpose-built solutions to accounting firms and their clients,” said Gary Engel, Executive Vice President of Cloud Products at Right Networks. “We are excited to partner with a team that shares the same vision for moving the accounting industry forward through innovation.”
SmartVault document management software enables firms to standardize their document-based workflows, supporting cost reduction, increased productivity and the ability to deliver higher service levels to their clients. Email is still widely used in the profession to route documents. A document management system like SmartVault, paired with Right Networks, offers firms a far more secure way to request, store, e-sign and share files—enabling the business controls required across the full document lifecycle. This is an essential component of meeting regulatory compliance mandates.
“Partnering with Right Networks creates a powerful synergy that further supports the unique security and workflow needs of the accounting profession. We are confident that it will continuously improve the everyday lives of our customers and their clients,” said Dania Buchanan, President of SmartVault. “The feedback from our shared customers is already proving that the pairing of our solutions delivers clear value and satisfies the need for business efficiency and higher levels of security when working with documents.”
To learn more about the Right Networks and SmartVault partnership or to see the integration in action, visit the Right Networks booth (#C23) and SmartVault booth (#B12) at QuickBooks Connect 2022.
Accounting & Audit
Jason Bramwell
Accounting & Audit
Accounting & Audit
Jason Bramwell
Accounting & Audit
Subscribe for free and get unlimited access to all CPA Practice Advisor content
Subscribe
CPAPA is registered with the National Association of State Boards of Accountancy (NASBA) as a sponsor of continuing professional education on the National Registry of CPE Sponsors.
© 2023 Firmworks, LLC. All rights reserved
- Published in Uncategorized
$8000+ Mn, Intelligent Document Processing Market Size to Grow at … – GlobeNewswire
October 12, 2022 09:00 ET | Source: The Insight Partners The Insight Partners
Pune, INDIA
New York, Oct. 12, 2022 (GLOBE NEWSWIRE) — The Insight Partners published latest research study on “Intelligent Document Processing Market Size, Share, Growth, Industry Trends and Forecast to 2028,” the global intelligent document processing market size is expected to grow from USD 1,022.73 million in 2021 to USD 8,045.81 million by 2028, with an estimated CAGR of 34.6% from 2022 to 2028.
Download Sample PDF Brochure of Intelligent Document Processing Market Size – COVID-19 Impact and Global Analysis with Strategic Insights at: https://www.theinsightpartners.com/sample/TIPRE00028611/
Global Intelligent Document Processing Market Report Scope, Segmentations, Regional & Country Scope:
Global Intelligent Document Processing Market: Competitive Landscape
ABBYY; IBM Corp; Kofax Inc.; Datamatics Global Services Limited; Appian; WorkFusion, Inc.; Parascript; Open Text Corporation; Hyland Software, Inc.; and Extract Systems are among the key intelligent document processing market players profiled during the intelligent document processing market study. Several other major companies were studied and analyzed during this research study to get a holistic view of the intelligent document processing market and its ecosystem.
Inquiry Before Purchase: https://www.theinsightpartners.com/inquiry/TIPRE00028611/
Companies in the intelligent document processing market offer different products for various types of document processing. These products help streamline document and data flow, which helps in ensuring swift decision-making. For instance, in the retail industry, these products offer measurable and consistent business value to processes such as customer correspondence and claims, sales order processing, and accounts payable. The document processing platform reads the unstructured documents, further redacting or extracting the information the customer needs, and routes the data to the final destination. The document processing offered by the companies in the market lessens the time spent manually, reduces human error typically caused by manual data entry, and offers fast access to valuable discrete data that customers can compare, share, report, and analyze, contributing to the intelligent document processing market growth.
The rising demand for the extraction of insights from unstructured data is catalyzing the growth of the intelligent document processing market. The awareness related to the advantages of intelligent document processing solutions is maximum among large enterprises, which generate enormous amounts of data daily. These large enterprises invest substantial amounts toward enhancing the respective business process and optimizing the efficiency of the business. Thus, the demand for intelligent document processing solutions among large enterprises is on a constant rise, which is allowing the intelligent document processing market players to experience growth in respective sales, ultimately driving the intelligent document processing market.
Speak to Research Expert – https://www.theinsightpartners.com/speak-to-analyst/TIPRE00028611
Most business data in recent years is unstructured, and end users face significant challenges in gathering meaningful insights from the data. The data is represented in various modules, including documents, emails, spreadsheets, audio & visual, presentations, images, and web searches. In order to gain maximum information from unstructured data, several end users or industries are opting for intelligent document processing solutions, which facilitates them in extracting important insights.
In the intelligent document processing market, end-use industries such as BFSI and manufacturing, and government- across the different regions have attributed in the solution popularity. For instance, the strong presence of manufacturing and BFSI sectors in China and India has witnessed substantial demand for robust and efficient document processing tools in the past few years. North America holds the highest share in the intelligent document processing market as most of the companies in the region have already shifted to digital transformation to compete effectively in the global intelligent document processing market.
Furthermore, several other countries are increasing their adoption of digital transformation technology to compete effectively in the global market and increase revenue growth. Moreover, the demand for document processing solutions is predicted to grow during the forecast period, owing to the need for automated operations from manufacturing industries in several emerging economies of APAC, contributing to the intelligent document processing market growth in the region.
Quickly Purchase Premium Copy of Global Intelligent Document Processing Market Growth Report (2022-2028) at: https://www.theinsightpartners.com/buy/TIPRE00028611/
Browse Adjoining Reports:
Document Imaging Market Forecast to 2028 – COVID-19 Impact and Global Analysis by Component (Hardware, Software); Deployment Type (Cloud, On-premises); End-user (Educational Institutions, Government, Enterprises, Law Firms, Others) and Geography
Document Reader Market Forecast to 2028 – COVID-19 Impact and Global Analysis By Product Type (Passport, E-Passport, Visa, IDs, Licenses, Others); Technology (NFC/RFID, Barcode, Contact SmartCard, Others); Application (Border Crossings, Airports, Train/ Bus Terminals, Banks, Travel agencies, Others) and Geography
Document Analysis Market to 2027 – Global Analysis and Forecasts by Solutions (Products and Services); Deployment Type (Cloud and On-premise); Organization Size (Large Enterprises and Small & Medium Enterprises (SMEs)); Industry Vertical (BFSI, Government, Healthcare, Retail, Manufacturing, and Others)
Document Management Software Market Forecast to 2028 – Covid-19 Impact and Global Analysis – by Component (Solutions, Services), Deployment Mode (On-Premise, Cloud-Based), Organization Type (SME and Large Enterprise), Application (Healthcare, BFSI, Government, Education, Retail, and others) and Geography
Document Drafting Platform Market Forecast to 2028 – COVID-19 Impact and Global Analysis By Deployment Type (Cloud, On Premise); End User (Individual, Enterprise) and Geography
Medical Document Management Systems Market Forecast to 2028 – Covid-19 Impact and Global Analysis – By Application (Image Management, Patient Medical Records Management, Admission and Registering Documents Management, Patient Billing Documents Management); Solution (Document Scanning Software, Document Management Software); Mode of Delivery (Cloud Based, Web Based, On – Premise Model); End User (Hospitals and Clinics, Insurance Providers, Nursing Homes, Other End Users) and Geography
Document Scanner Market Forecast to 2028 – Covid-19 Impact and Global Analysis – by Product Type (Sheetfed Scanners, Handheld, Flatbed); Enterprise Size (SMEs, Large Enterprises); Industry Vertical (BFSI, IT and Telecom, Healthcare, Education, Transportation and Logistics, Others) and Geography
Document Camera Market Forecast to 2028 – COVID-19 Impact and Global Analysis by Connection Type (Wired, Wireless); End-Use (Education, Corporate, Others) and Geography
Medical Record Management Market Forecast to 2028 – Covid-19 Impact and Global Analysis – by Component (Software, Services); Application (Patient Record Management, Admission and Registration Document Management, Patient Billing Document Management, Others); Deployment (Cloud, On-Premise); End User (Hospitals and Clinics, Nursing Homes, Healthcare Payers, Others) and Geography
About Us:
The Insight Partners is a one stop industry research provider of actionable intelligence. We help our clients in getting solutions to their research requirements through our syndicated and consulting research services. We specialize in industries such as Semiconductor and Electronics, Aerospace and Defense, Automotive and Transportation, Biotechnology, Healthcare IT, Manufacturing and Construction, Medical Device, Technology, Media and Telecommunications, Chemicals and Materials.
Contact Us:
If you have any queries about this report or if you would like further information, please contact us:
Contact Person: Sameer Joshi
E-mail: sales@theinsightpartners.com
Phone: +1-646-491-9876
Press Release: https://www.theinsightpartners.com/pr/intelligent-document-processing-market
Industry Research: https://www.biospace.com/employer/2309254/tip-knowledge-services-pvt-ltd-/
- Published in Uncategorized
Everything You Need to Know About Version Control – Spiceworks News and Insights
Version control tracks the progress of code across development and iterations and also aids in managing changes during the lifecycle.
Version control is a system that tracks the progress of code across the software development lifecycle and its multiple iterations – which maintains a record of every change complete with authorship, timestamp, and other details – and also aids in managing change. This article details how version control in DevOps works, the best tools, and its various advantages.
Version control is defined as a system that tracks the progress of code across the software development lifecycle and its multiple iterations – which maintains a record of every change complete with authorship, timestamp, and other details – and also aids in managing change.
The process of monitoring and managing changes to software code is known as version control, also sometimes referred to as revision control or source control systems. Software technologies called version control systems assist software development teams in tracking changes to source code over time.
Version control systems enable software teams to operate more swiftly and intelligently as development environments have increased. They are beneficial for DevOps teams because they will allow them to speed up successful deployments and reduce development time.
Version control pinpoints the trouble spots when developers and DevOps teams work concurrently and produce incompatible changes so that team members can compare differences or quickly determine who committed the problematic code by looking at the revision history. Before moving on with a project, a software team can use version control systems to resolve a problem.
Software teams can understand the evolution of a solution by examining prior versions through code reviews. Every alteration to the code is recorded by version control software in a particular type of database. If an error is made, developers can go back in time and review prior iterations of the code to remedy the mistake while minimizing disturbance for all team members.
Collaboration among employees, keeping several iterations of information created, and data backup are just a few issues that any global organization may encounter. For a business to succeed, developers must overcome each of these issues. A version control system is then necessary for this situation.
The first version control system was mainframe-based, and each programmer used a terminal to connect to the network. The first server-based, or centralized, version control systems that utilized a single, shared repository were introduced on UNIX systems; later, these systems were made accessible on MS-DOS and Windows.
Versions can be recognized by labels or tags, and baselines can be used to mark approved versions or versions that are particularly important. Versions that have been checked out can be used as a branching point for code from the main trunk by various teams or individuals. The first version to check in will always win when versions are checked out and checked in.
Some systems may offer version merging if other versions are checked out so that one can upload new modifications to the central repository. Branching is a distinct approach to version control where development programs are duplicated for parallel versions of development while keeping the original and working on the branch or making separate modifications to each.
Each copy is called a branch, and the original program from where it was derived is known as the trunk, the baseline, the mainline, or the master. Client-server architecture is the standard model for version control. Another technique is distributed version control, where all copies are kept in a codebase repository, and updates are made by sharing patches or modifications across peers. Version control allows teams to work together, accelerate development, settle issues, and organize code in one place.
See More: What Is Jenkins? Working, Uses, Pipelines, and Features
Globally, version control systems comprise a multi-billion-dollar industry, poised to reach $716.1 million by 2023 (as per MarketsAndMarkets research). In this massive market, 13 tools stand out. They are:
Software that carries out software version control, configuration management, and change management tasks is known as Configuration Management Version Control (CMVC). This system was client-server based, with servers for several Unix flavors and command-line and graphical clients for many platforms. Even after renaming a file, it can track file history. This is because developers may alter the database filename and the filename on the disk was a number. Delegating power is possible thanks to its decentralized administration.
Git is among the most powerful version control programs now on the market. The creator of Linux, Linus Torvalds, created the distributed version control system known as Git. Its memory footprint is minimal and can follow changes in any file. When you add this to its extensive feature set, you get a full-featured version control system that can handle any project. Due to its simple workflow, it is employed by Google, Facebook, and Microsoft.
A version control system called Apache Subversion, which is free and open-source, enables programmers to manage both the most recent and previous iterations of crucial files. It can track modifications to source code, web pages, and documentation for large-scale projects. Subversion’s main features are workflow management, user access limits, and cheap local branching. Both commercial products and individual projects can be managed using Subversion, a centralized system with many powerful features. It is one of Apache’s many open-source solutions, like Apache Cassandra.
You can utilize all Azure DevOps services or just the ones you require to improve your current workflow. A group of software development technologies you can use in conjunction is Azure DevOps Server, formerly Team Foundation Server (TFS). In addition to access controls and permissions, bug tracking, build automation, change management, collaboration, continuous integration, and version control are all elements of the source code management program known as Azure DevOps Server.
One of the first version control systems developed, CVS is a well-known tool for open-source and commercial developers. You can use it to check in and out the code you intend to work on. Teams can integrate their code modifications and add distinctive features to the project. CVS uses delta compression to effectively compress version differences and a client-server architecture to manage change data. In larger projects, it saves a lot of disk space.
See More: What Is Serverless? Definition, Architecture, Examples, and Applications
Developers and businesses adore Mercurial for its search capabilities, backup system, data import and export, project tracking and management, and data migration tool. The free source control management program Mercurial supports all popular operating systems. It is a distributed versioning solution and can easily manage projects of any size. Through extensions, programmers can quickly expand the built-in functionality. For software engineers, source revisioning is made simpler by its user-friendly and intuitive interface.
Software development teams may collaborate and keep track of all code changes using GitHub. You can keep track of code modifications, go back in time to correct mistakes, and collaborate with other team members. The most reliable, secure, and scalable developer platform in the world is GitHub. You receive the best resources and services to assist you in creating the most cutting-edge communities possible. The most reliable, secure, and scalable developer platform in the world is GitHub.
Private Git repositories are hosted by the managed version control system AWS CodeCommit. It smoothly integrates with other Amazon Web Services (AWS) products, and the code is hosted in secure AWS settings. Therefore, it’s a suitable fit for AWS’s current users. Access to various helpful plugins from AWS partners is also made available through AWS integration, aiding in program development. You don’t have to worry about maintaining or scaling your source control system when you use CodeCommit.
As a component of the Atlassian software family, Bitbucket can be connected with other Atlassian products like HipChat, Jira, and Bamboo. Some of Bitbucket’s key features are code branches, in-line comments and debate, and pull requests. The company’s data center, a local server, or the cloud can all be used for its deployment. With Bitbucket, you can freely connect with up to five people. This is advantageous because you can use the platform without spending any money.
RhodeCode is a platform for managing public repositories. RhodeCode offers a contemporary platform with unified security and tools for any version control system, in contrast to old-fashioned source code management systems or Git-only tools.
The platform is designed for behind-the-firewall enterprise systems that require high levels of security, sophisticated user management, and standard authentication. RhodeCode has a convenient installer, it may be used as a standalone hosted program on your server, and its Community Edition is unrestrictedly free.
CA Panvalet establishes and maintains a control library of source programs, centralizes the storage of the source, and offers quick access for maintenance, control, and protection against loss, theft, and other perils. Like Microsoft Visual SourceSafe for personal computers, Panvalet is a closed-source, proprietary system for controlling and versioning source code. Users check out files to edit and then check them back into the repository using a client-server architecture.
It offers the sole source of accuracy for all development. The company behind it is Perforce Software Inc. It is a networked client-server revision control tool. It supports several operating systems, including OS X, Windows, and Unix-like platforms. This tool is primarily used in large-scale development setups. Through the tracking and management of changes to source code and other data, it streamlines the development of complicated products. Your configuration changes are branched and merged using the Streams feature.
GNU Bazaar (formerly Bazaar-NG Canonical) is a command-line utility by the company that created Ubuntu, and it is a distributed and client-server revision control system. Numerous contemporary projects use it, including MySQL, Ubuntu, Debian, the Linux Foundation, and Debian. GNU Bazaar is truly cross-platform, running on every version of Linux, Windows, and OS X. High storage efficiency, offline mode support, and external plugin support are some of GNU Bazaar’s finest qualities. Additionally, it enables a wide range of development workflows.
Using a version control system, one can obtain the following benefits:
Benefits of Version Control
It goes without saying that team members should work simultaneously, but even individuals working alone can profit from being able to focus on separate streams of change. By designating a branch in VCS tools, developers and DevOps engineers can keep several streams of work separate while still having the option to merge them back together to ensure that their changes don’t conflict.
Many software development teams use the branching strategy for every feature, every release, or both. Teams have various workflow options to select from when deciding how to use the branching and merging features in a VCS.
The development of any source code is continuous in the modern world. There are always more features to be added, more people to target, and more applications to create. When working on a software project, teams frequently have various main project clones to build new features, test them, and ensure they work before uploading this new feature to the main project. Due to the ability to develop several sections of the code concurrently, this could save time.
The team tasked with the project consistently generates new source codes and makes changes to the already existing code. These modifications are kept on file for future use and can be consulted if necessary to determine the true source of a given issue. If you have a record of the changes made in a particular code file, you and new contributors may find it easier to comprehend how a specific code section came to be. This is vital for working efficiently with historical code and allowing developers to predict future work with accuracy.
This refers to every modification made over time by numerous people. File addition, deletion, and content modifications are all examples of changes. The ease with which various VCS programs handle file renaming and movement vary. You should also include the author, the date, and written comments outlining the rationale behind each change in this history.
The ability to go back to earlier iterations allows for the root cause study of faults, which is essential when fixing issues with software that is more than a few years old. Nearly everything can be regarded as an “earlier version” of the software if it is still being developed.
Since pushing and pulling cannot be done using a distributed version control system without an internet connection, most development can be done on the go, away from home, or in an office. Contributors will make changes to the repository and can view the running history on their hard drives.
With more flexibility, the team can resolve bugs with a single change-set, increasing developers’ productivity. Developers can do routine development tasks quickly with a local copy. With a DVCS, developers can avoid waiting on a server to do everyday activities, which can impede delivery and be inconvenient.
See More: Top 10 DevOps Automation Tools in 2021
Whenever a contributor copies a repository using a version control system, they are essentially making a backup of the repository’s most recent version, which is probably its most significant advantage. We can protect the data from loss in the event of a server failure by having numerous backups on various workstations.
Unlike a centralized version control system, a distributed version control system does not rely on a single backup, increasing the reliability of development. Although it’s a widespread fallacy, having numerous copies won’t take up much space on your hard drive because most development involves plain text files and most systems compress data.
An open line of communication between coworkers and teams results from version control because sharing code and being able to track past work results in transparency and consistency. It makes it possible for the different team members to coordinate workflow more straightforwardly. There are repercussions from this better communication.
Team members can operate more productively as a result of effective workflow coordination. They can more easily manage changes and work in harmony and rhythm. This presents the many team members as a single entity that collaborates to achieve a particular objective.
Management can get a thorough picture of how the project is doing thanks to version control. They know who is responsible for the modifications, what they are intended to accomplish when they are completed, and how the changes will affect the document’s long-term objective. It helps management spot persistent issues that particular team members could bring on.
The accurate change tracking provided by version control is a great way to get your records, files, datasets, and/or documents ready for compliance. To manage risk successfully, keeping a complete audit trail is essential. Regulatory compliance must permeate every aspect of a project. It requires identifying team members who had access to the database and accepting accountability for any changes.
The seamless progress of the project is ensured by version management. Teams can collaborate to simplify complex processes, enabling increased automation and consistency and progressive implementation of updated versions of these complex procedures. The updated versions allow programmers to revert to a previous version when errors are found. Testing is simpler if you go back to an earlier version because bugs are caught sooner and with less user impact.
Having many outdated versions of the same document can be prevented with version management. Errors brought on by information displayed inconsistently across different papers will therefore be diminished. One should convert absolute versions of documents to a “read-only” state after the evaluation is complete. It will restrict the possible modifications and leave little possibility for mistakes in the future.
See More: DevOps vs. Agile Methodology: Key Differences and Similarities
Version control systems are a vital component of modern-day software development. It helps maintain a reliable source code repository and ensures accountability no matter who works on the code. It also makes finding and addressing bottlenecks easier by simplifying the root cause analysis process. Ultimately, version control enables a single pane of glass for collaborative and iterative application development in short release cycles.
Did this article tell you all you needed to know about version control? Tell us on Facebook, Twitter, and LinkedIn. We’d love to hear from you!
Technical Writer
- Published in Uncategorized
Best practices for construction document management – Planning, BIM & Construction Today

Many contractors use a mix of paper and digital documents, and even if they’ve gone fully digital, they may rely on several different software applications. Many contractors still rely on basic digital tools like spreadsheets to manage their projects.
On the whole, this trend toward digital is good. It means contractors want to make documents more accessible to their teams. But for real success with document control in construction to happen, we need to identify what that work encompasses and focus on solving the remaining challenges of document storage and accessibility.
Construction document management is the general process that a construction manager or project manager might use to organise and store contracts, blueprints, permits, and other documents necessary to day-to-day operations.
These days, filing cabinets have been replaced in many businesses with construction software that digitises data and helps to store and share it quickly with those who need it in the field via electronic forms, dashboards, plans, drawings, specs and much more.
Construction document management styles may differ from individual to individual, but the best practices we’ve laid out below can help construction managers identify the best ways to ensure no one is left hanging when they need information.
Document management is not a trivial thing. These documents play a fundamental role in construction. But many common challenges arise related to document management, even in modern construction organisations:
The first step to getting a handle on document management at your organisation is to centralise your data and documents. A connected, cloud-based software solution that provides access to the most current project documents in real-time makes it easier for all members of your project teams to find what they need and execute a project correctly.
At Trimble Viewpoint, we often discuss the importance of having one accurate data source, and document management is no exception. How can you confidently say things will be done correctly unless everyone uses the same information?
Organising a tricky file structure can be made easier by swapping out paper records for digital files. In particular, those that can be updated through your construction software system in real-time to present the latest information are easier for multiple stakeholders to access.
Construction document management software that connects all of the necessary components of a project is crucial for successful teams.
Next, you must make documentation readily available to everyone on your project team who needs it. Cloud-based document storage and connected construction workflows allow your team to access needed data and documents in the field, often through mobile-friendly applications that work directly on smartphones or tablet devices.
Viewpoint For Projects, for example, can be accessed both by using a computer in the office, or a tablet or smartphone out in the field, providing the same degree of functionality no matter where work takes construction professionals.
This allows for real-time sharing and viewing of important documents. It has a customisable folder structure, so it’s simple to navigate and includes a complete version history and audit trail to see who’s made changes to documents. Viewpoint For Projects users can also mark up PDFs in their browser, so it’s easy to leave notes and get questions answered.
After you have centralised your data with a connected software suite and provided remote access to those who need that information most, it’s time to coordinate how information moves from one team member to another — and to standardise these workflows for all construction project data.
Ensure that the following assets and processes are in place:
Too many software systems that don’t integrate can become difficult to coordinate and optimise document management workflows. Ultimately, it can cause the same efficiency problems you were trying to solve in the first place.
However, with a connected, cloud-based construction management suite, most of the aforementioned workflows are built into the data and documentation capabilities. For instance, financial data entered into accounting workflows can auto-populate project management forms or reports and vice versa.
A centralised, reliable document management solution ultimately enables better collaboration for everyone working on your projects and gives you more control over documentation. You won’t have to worry about inaccurate data floating around and leading to mistakes on your job sites.
Once you connect your data and document workflows in real-time, you’ll be surprised just how much easier your daily tasks are to complete, how much smoother your projects go, and how much more profitable your business is.
document.getElementById( “ak_js_1” ).setAttribute( “value”, ( new Date() ).getTime() );
- Published in Uncategorized
API Evolution Without Versioning with Brandon Byars – InfoQ.com
Live Webinar and Q&A: Panel: 2023 Data Engineering Trends and Predictions (January 19, 2023) Save Your Seat
Facilitating the Spread of Knowledge and Innovation in Professional Software Development
Windows Services play a key role in the Microsoft Windows operating system, and support the creation and management of long-running processes. When “Fast Startup” is enabled and the PC is started after a regular shutdown, though, services may fail to restart. The aim of this article is to create a persistent service that will always run and restart after Windows restarts, or after shutdown.
Everyone likes the idea of building something new. So much freedom. But what about making changes after you have users? In this episode, Thomas Betts talks with Brandon Byars about how you can evolve your API without versioning, a topic he spoke about at QCon San Francisco.
Sara Bergman introduces the field of green software engineering, showing options to estimate the carbon footprint and discussing ideas on how to make Machine Learning greener.
Software engineers should accept their responsibility to take energy consumption and carbon dioxide emissions into account when developing software, they have a big responsibility towards nature, our environment and sustainability. This article sheds light on how software engineers can this perspective into account, zooming in on energetic shortcomings or bottlenecks of bugs.
GitHub Actions is an effective CI tool. However, integrating it into enterprise organizations can be challenging. This article looks at best practices for GitHub Actions in the enterprise.
Learn how to achieve high-level observability without picking and choosing which logs to collect. Register Now.
Adopt the right emerging trends to solve your complex engineering challenges. Register Now.
Your monthly guide to all the topics, technologies and techniques that every professional needs to know about. Subscribe for free.
InfoQ Homepage Podcasts API Evolution Without Versioning with Brandon Byars
Jan 09, 2023
Podcast with
by
Everyone likes the idea of building something new. So much freedom. But what about making changes after you have users? In this episode, Thomas Betts talks with Brandon Byars about how you can evolve your API without versioning, a topic he spoke about at QCon San Francisco.
Teleport is the easiest, most secure way to access infrastructure. Get started today.
Transcript
Hi everyone. Registration is now open for QCon London 2023 taking place from March 27th to the 29th. QCon International Software Development Conferences focus on the people that develop and work with future technologies. You'll learn practical inspiration from over 60 software leaders, deep in the trenches, creating software, scaling architectures, and fine tuning their technical leadership to help you adopt the right patterns and practices. Learn more at qconlondon.com.
Thomas Betts: Everyone likes the idea of building something new, so much freedom. But what about making changes after you have users? Today I'm talking with Brandon Byers about how you can evolve your API without versioning the topic he spoke about at QCon San Francisco. Brandon is a passionate technologist, consultant, author, speaker, and open source maintainer. As head of technology for Thoughtworks North America, Brandon is part of the group that puts together the Thoughtworks technology radar, a biannual opinionated perspective on technology trends. He is the creator of Mountebank, a widely used service virtualization tool and wrote a related book on testing microservices. Brandon, welcome to the InfoQ podcast.
Brandon Byars: Oh thanks. Happy to be here.
Thomas Betts: I set this up a little in the intro. Let's imagine we have a successful API and it's in use by many people and other services calling it, but now it's time to make a change. In general, if we're adding completely new features, that's easy, but when we need to change something that's already being used, that's when we run into trouble. Why is that so difficult and who's impacted by those changes?
Brandon Byars: Yes, it's a really hard problem and often the pain of absorbing the change is often overlooked. So let's start with that second question first. The API consumers, when you see a new major version, regardless of how that's represented as an API versioning or SemVer or some equivalent, that's indicative of breaking changes because the API producer wanted to either fix something or change the contract in a breaking way, that is work for you to consume. And that work is oftentimes easy to overlook because it's federated amongst the entire population of API consumers. And a lot of times you don't even have a direct connection with them for a public API like Mountebank as a public command line tool and it's a hybrid REST API with some interesting nuance behind it.
The standard strategy that you always hear about is versioning and of course versioning works. You can communicate to the consumers that they need to change their code to consume the breaking changes in the contract. But that is work, that is friction. And what I tried to do very intentionally with Mountebank, which is open source, so I had a bit more room to play, it's just a volunteer project, was really try to come up with strategies outside of versioning that make that adoption easier because you're not frustrated with changes over time. And Mountebank itself is nine-years-old. It, itself, depends on APIs. It's a node JS project, so it depends on node JS libraries.
And I've spent more volunteer nights and weekends time than I care to admit not adding features, simply keeping up with changes to some of the library APIs that had breaking changes because they legitimately cleaned up their interface but they cleaned up the interface at the cost of me doing additional work and that adds up over time. And so I really pushed hard to come up with other strategies that still allow me to improve the interface over time or evolve it in ways that would typically be a breaking change, but without forcing the consumers to bear through the work associated with that breaking change.
Thomas Betts: And I like how you mentioned in that case, were a consumer that's also a producer. A lot of us, software developers straddle both lines. We're creating something that someone else consumes and sometimes that's a customer facing product, it's a UI, but sometimes it is an API that's a product, which is more like what you're describing with Mountebank.
Brandon Byars: Yes, of course, API is a broad term, application programming interface. So I mentioned no JS libraries, those are in process and the JavaScript function definition for example might be the interface. Mountebank has a REST API, but it also has an embedded programmable logic inside of it that is similar to what you might expect as a Java function interface because you can pass in Java functions inside it as well. So it works on a couple different levels of that. But you're absolutely right, it is a API, it's a product released publicly. I don't have a direct line of communication to each of the individual users of it. I do have a support channel, but I would prefer, for my own sanity, that they don't use the support channel for just simple upgrade options. I would prefer to take that work off of both them and me in terms of the hand holding around it.
Thomas Betts: And so what exactly is Mountebank and then why was it a good system that allowed you to explore these ways of how to evolve an API?
Brandon Byars: Mountebank is what's called a service virtualization tool. And that phrase I stumbled across after writing Mountebank, I hadn't come across it previously that I considered it an out of process stub. So if you're familiar with a JMock, or one of those mocking tools that's in process stubbing, this allows you to take that out of process. So if I want to have black box tests against my application and my application has run time dependencies on another service that another team maintains, perhaps, anytime I run my tests against that service, I need an environment where both my application and the service are deployed. Especially if another team is controlling the release cycle of that dependency, then you can introduce non-determinism into your testing.
And so service virtualization allows you, and testing your application to directly control the responses from the dependent service so that you can test both happy paths, and it's much easier to test exceptional scenarios once you understand what the real service should respond like in those exceptional scenarios to test the sad paths as well, allowing you a lot more flexibility and test data set up, test determinism.
And of course, it still needs to be balanced with other tests approaches like contract testing to validate your environmental assumptions. But it allows you to give higher level tests, integration or service or component tests with the same type of determinism that we're used to in process.
So why is it a good platform for exploring these concerns? Part of that is just social. It's a single owner open source product. I manage it so I have full autonomy to experiment, is also because of the interesting hybrid nature of it that I mentioned previously where it's both the REST API that you can start up with or the command line interface that listens on a socket and exposes arrest API and of course, it can spin up other sockets because those need to be the virtual services that you're configuring.
And the programmable nature of it where you can pass in certain JavaScript under certain conditions that try to cover off security concerns allows for some really interesting evolutions of both what you would normally represent on something like an OpenAPI specification. And recognize an OpenAPI specification will never be rich enough to give you the full interface of the programmable interface that's embedded inside the REST interface. So it allowed me to explore a lot of nuance around what it means to provide an API specification and have the autonomy to do that. And a tool that I was fortunate had some pretty healthy adoption early on. So I was doing this in the face of real users or in the natural course of work with real users not trying to do something artificial that was just a science experiment on the side.
Thomas Betts: So one of the things we usually talk about APIs, we describe them as contracts, but I remember in your QCon talk, you said that the better word was promises. Can you explain the difference there?
Brandon Byars: Yes, and it's really just trying to set expectations with users the right way, and have a more nuanced conversation around what we mean by the interface of an API. So we talk about contracts and we have specifications and of course, if you remember, we went through that awkward transition from SOAP to REST in 2008-era time frame, we really didn't have any specification language for REST. There was a lot of backlash against WSDL for SOAP. It was very verbose and so we went for a few years without having some standard like what Swagger ultimately became.
So we had some room in my career that I was part of where we experimented without these contracts, but we obviously still had an interface and we would document that maybe on wikis or whatever that might be to try to give consumers an indication of how to use the API. We could get so far with that, it still had flaws in it. And so we filled that hole appropriately with tools like Swagger OpenAPI. There were other alternatives that allowed us to communicate with consumers in a way that allowed us more easily to builds STKs that allowed generic tools like the graphical UI that you might see on a webpage that described the documentation around it for Swagger docs, but it's never rich enough to really define the surface area of the API.
And that is particularly true when you have a complex API like Mountebank with an embedded programmable interface inside of it, because now you're talking about what is just a string on the JSON interface. But inside that string might be a function declaration that also has to have a specific interface for it to work inside the JavaScript context that it's executed inside of. And that's an example, but it's a more easily spotted example than what tends to happen even when you don't have a programmable interface, because you still have edge cases of your API that are always difficult to demonstrate through the contract.
And this idea of promises came out of the configuration management world. Mark Burgess, who helped create CFEngine, one of the early progenitors to Puppet and Chef and the modern infrastructure-as-code practices, defined a mathematical theory around promises that allowed him to build CFEngine. But it was really also a recognition that promises can be broken in the real world. When I promise you something, what I'm really signaling is I'm going to make a best faith effort to fulfill that promise on your behalf. And that's a good lens to think about APIs because under load, under exceptional circumstances, they will respond in ways that the producers could not always predict. And if we walk into it with this mentality, this architectural ironclad mentality that the contract directly specifies with the API is, how it's going to behave, we're missing a lot of nuance. It allows us to have richer conversations around API evolution.
Thomas Betts: I want to go back, you said there's a lot about communication and that's where you got in your talk about the evolution patterns and different ways to evolve an API. You had criteria and communication seemed to be the focal point of that and architects love to discuss trade-offs. What are the important tradeoffs and evaluation criteria that we need to consider when we're looking at these various evolution patterns?
Brandon Byars: There's an implicit one and I didn't talk about it much because it's the one that everybody's familiar with and that is implementation complexity. A lot of the times, we version APIs because we want to minimize implementation complexity and the new version, the V2, allows us to delete a bunch of now dead code so that we, as the maintainers of it, don't have to look at it.
What I tried to do was look at criteria from a consumer's perspective and the consumers don't care what the code inside your API looks like.
I listed three dimensions. The first one I called obviousness. A lot of times goes by the name and the industry of the principle of least surprise. Does the API and the naming behind the fields and the nesting structure and the endpoint layout, does it match your intuitive sense of how an API should respond? Because that eases the adoption curve. That makes it much easier to embrace and you always have the documentation as a backup, but if it does what you expect, because we, as developers or tinkerers, we're experimenters, that's how we learn how to work through an API. Obviousness goes a long way towards helping us adopt it cleanly.
I listed a second one that I called elegance, which is really just a rough proxy for usability and the learning curve of the API, consistency of language, consistency of style, the surface area of the API. A simple way to avoid versioning for example is to leave Endpoint1 and just call it Endpoint1V2 and have a separate endpoint, that allows you to not version. And it's a legitimate technique, but it decreases elegance because now you have two endpoints that the consumer has to keep in mind and have some understanding of the evolution of the API over time as an example.
And then the third one is stability, which is how much effort a consumer has to put in to keeping up with changes of the API over time. And of course, versioning that's stable within the version, but oftentimes requires effort to move between versions. Some of the techniques that I talked about in the talk meet stability to varying degrees. Sometimes, it can't be a perfect guarantee of stability. This is where the promise notion kicks in, but can make a best faith effort of providing a stable upgrade path to consumers.
Thomas Betts: So that gets us to the meat of your talk was about these evolution patterns. I don't know if we'll get through all of them, but we'll step through as many as we can in our time. The first was change by addition, which the intro I said is considered the easy and safe thing to do. But can you give us an example and talk about the pros and cons of when you would or wouldn't want to change by addition?
Brandon Byars: Yes, the simplest example is just adding a new field. It's simply adding a new object structure into your API and that it should not be a breaking change for consumers. Of course, there are exceptions where it will be if they have strict deserializion turned on and configure their deserializer and throw errors if it sees the field it doesn't recognize. But in general, we have to abide by what's known as Postel's Law, which says that you should be strict in what you send out and liberal in what you accept. And that was a principle that helped scale the internet.
Postel was involved in a lot of the protocols like TCP that helped to scale the internet. And it's a good principle to think in terms of API design as well or having a tolerant reader. A more controversial example might be the example I just gave, which is if we have Endpoint1 and I decided that I got something wrong about Endpoint1 about the behavior, but I don't want to create a new version, I just create Endpoint1V2 as a separate endpoint. And so that's a new change. It's a change by addition, but it's an inelegant one because it means now, consumers have to understand the nuance between these two endpoints. So it increases the surface area for the same capability fundamentally of the API.
Thomas Betts: Yes, I can see that. GetProducts and GetProductsV2 and it returns a different type. And then what do you do with the results if you want to drill into it and that can quickly become a spaghetti pile of mess. The next one was multi-typing and what does that look like in an API?
Brandon Byars: Yes, so I did this one time in Mountebank and I regretted it because I don't think it's a particularly obvious or elegant solution, but I had added a field that allows you to specify some degree of latency in the response from the virtual service at just a number of milliseconds that you wait. And then somebody asked to be able to make the number of milliseconds dynamic. And so I mentioned in passing this programmable embedded API inside the REST API, there was a way of passing a JavaScript function, in another context. So I decided that was a solution that sort of fit within the spirit of Mountebank, but because I didn't want to have the GetProducts and GetProductsV2 endpoint, so I didn't want to have a Wait behavior is what it's called, and a WaitDynamic behavior at the time. I just overloaded the type of the Wait behavior.
So if you pass a number, it interprets it as milliseconds. If you pass something that can't be interpreted as a number, it expects it to be this JavaScript function that will output the number of milliseconds to wait and that works without having to add a new field. But it's a clumsy approach in retrospect because it makes building a client SDK harder. That's a unexpected behavior of the API. So in retrospect, I would've gone with a less elegant solution that increase the surface area of the API to just make it more obvious to our consumers.
Thomas Betts: The idea of having an overload makes sense when it's inside your code. I write C# mostly and I can overload a function with different parameters and specified defaults and that's intuitively easy to tell when it's inside your code. When you're getting to an API surface, that raises a level of complexity because of how we're communicating those changes, it's not as obvious. You don't necessarily know what language is going to be calling into your service and what they're able to do.
Brandon Byars: Yes, that's exactly right and that's why I mentioned it in passing because I did do it. That was one of the very first changes I made in Mountebank but regretted it and I don't think it's a robust strategy moving forward.
Thomas Betts: Yes, it's also a case of if you make all the decisions based on the best information you have at that point in time and the 500 milliseconds sounded like a good option but quickly ran into limitations. I think people can relate to that.
I know I've run into the next one myself and that's upcasting. So take a single string and oh, I actually want to handle an array of strings. How does that look in an API and do you have any advice on how to do that effectively?
Brandon Byars: Yes, upcasting is probably my favorite technique as an alternative to versioning. So the idea, the name, of upcasting is really this idea of taking something that looks like an old request and transforming it to the new interface that the code expects. And did something very similar to what you just described, had something that was a single string. It was this notion that I could shell out to a program that could augment the response that the virtual service returns, but quickly realized that that needed to be an array because people wanted to have a pipeline of middleware that other tools supported so they could have multiple programs in that list. And the way that I went about that in Mountebank was I changed the interface. So if you go to the published interface on the documentation site, it would list the array. That was the only thing that was documented.
Because this was the request processing pipeline, every request came through the same code path. So I was able to just insert one spot and that code path for all requests that said, "Check if we need to do any upcasting." And what it would do is it would go to that field and say, "Hey, is the type a string? If it is, then just wrap an array around that string." And so the rest of the code only had to care about the new interface. And so that made the implementation complexity. It reduced what having to scatter a lot of this logic all throughout the code, it was able to centralize it in one spot.
It also is really effective because you can nest upcasts. In fact, this happened in the example that we're talking about where it went from a string to an array and then, without getting too much detail, it actually needed to turn back to a string. But I needed to put an array at the outer level. And so I had to then have a second upcast that just said, "Hey, is this an array?" Turn it back to a string and is this outer thing an array or an object? And make sure it's the right type and go through the transformation to fix it if it's not.
But again, it's very simple and very deterministic because it all requests in the pipeline go through the same code pass. It'll centralize the logic and as long as you execute the upcasts in order in chronological order of when you made those changes, what would otherwise be versions, then it's a determinist output and you're accepting basically anybody who has any previous version of your API, it will still work. Even if it doesn't match what's documented as a published interface, if it matched what used to be documented, the code will transform it to the current contract itself.
And so that's a really powerful technique that balances those concerns that we talked about around obviousness, and elegance, and stability. It's a very stable approach. There still are edge cases where you can break a consumer if they're then retrieving the representation of this resource that has had its contract transformed to the upcast and that breaks some client code that they have. You can still imagine scenarios where that could happen, but it's quite stable and very elegant because it requires no additional work for the consumer to consume it.
Thomas Betts: Yes, that's a key point that you're trying to get to is minimizing the impact to the consumers. So having a version pushes the cost to them for this breaking change. But here, you're saying it is a breaking change but you are accepting the cost as the producer of the API.
Brandon Byars: Yes, and what I like so much about upcasting is that accepting the cost is centralized and easy to manage. And so whereas every consumer who used that field would've had to make that change with a new version. Only me as the producer has to make this change with an upcast and I can centralize it and it's not a lot of change. And I have all of the context around why the change happened because I'm the producer of the API so I can manage it in probably a safer way than a lot of consumers. I know where a lot of the mine fields that you might step on are during the transformation process itself.
Thomas Betts: Yes, I like the idea of having these versions. You talk about the versioning increasing the surface area of the API. It's also a matter of increasing the surface area of the code that you're maintaining. And here, by implementing that one upcast, it's in one place and it's very clear as opposed to now I've got the two endpoints, I've got double the code to maintain and how do I support that going forward? You've almost effectively deprecated the old one by assuming all of the functionality in the new one automatically.
Brandon Byars: Yes, so it's a clean technique because what you document as your published interface or contract is exactly what you would've otherwise done with a new version. It represents the new interface and the transformation code itself is very easy to manage with an upcast in my experience, at least with the upcasts I've done to date. And even when it's a complicated transformation, well that same transformation you would be asking your consumers to do were you to release a new version.
Thomas Betts: And like you said, this specifically, you changed the published specification. So you said, "I accept an array," but if someone still sent you a single string, which no longer abides by your published contract and you're like, "Oh, that's still good." And so it's no impact to them, but how do you resolve that discrepancy of, "Here's what I say works, but that's not just what I do." It's like an undocumented feature.
Brandon Byars: That's where you run some risk because now this undocumented feature, in fact a subsequent example that, hopefully we'll get to, tripped over this, those undocumented features can cause bugs. So you have to be thoughtful about that. You have to be careful. But it's part of the trade offs. We talked about architectural trade-offs and this is allowing us to have a clean interface that represents the contract we want without passing complexity to the consumers to migrate from one version to the next. So it reduces the friction of me changing the interface because I have to worry less about the cost of the consumers with it while maintaining the clean interface that I want as long as I don't run into too much risk of these hidden transformations causing bugs.
And in the case that we just talked about where it was simple type changes, I feel really confident that those don't cause bugs. The only bugs would be people round tripping the request and then getting the subsequent resource definition back into their code and doing some additional transformations in the client side. So there's broader ecosystem bugs that could happen, but then it's the same cost that the consumer would've had to do if I had released a new version. So it's not making their life any worse than a new version would.
Thomas Betts: And then you said that you just apply these in chronological order. So it's almost like a history. You have comments in there that say, "Hey, this was version zero or version one, then version two," and you can see the history of I had to do this and then I had to do that and then I had to do that. And so is your code self-documenting just for your benefit of, "Oh Yes, I remember that decision that I had to make and this is how I solved it."
Brandon Byars: Close. So I have a module called compatibility, and just in one spot in the request processing pipeline, I say Compatibility.Upcast() and I pass in the request. And then that upcast function calls a bunch of sub-functions. Every one of those sub-functions represents effectively aversion, a point in time. And so the first one might have been changed the string to an array and the second one might have been changed this outer structure into an object, whatever it is. But each of those are named appropriately and the transformation's obvious. And then the documentation, the comments and so forth around the code give you the context. And I just have the advantage of having it being a single maintainer, the advantage and disadvantage. There's other disadvantages of being a single maintainer, but the advantage is that I know all the history, so it's well contained and very easy to follow.
Thomas Betts: So that's a lot of talk about upcasting. What's the opposite of that? Downcasting?
Brandon Byars: Yes, downcasting is a little bit harder to think through. So this is taking something that looks like the new interface and making it look like the old interface. And I had to do this at a couple points in Mountebank's history and the implementation logic for this is more complex. The reason I had to do this is because of that embedded programmable API that I mentioned. So the REST API was the same, it just accepted the string. The string represented the JavaScript function that ran in a certain context. And over time, as often happens with functions where people are adding features over time as it just took on more and more parameters. And some of the parameters actually should be deprecated. So it's starting to look inelegant.
The usual solution for this in the refactoring world is you introduce a parameter object, like a config parameter, single parameter that has properties that represent all the historical parameters that were passed to the function. So I did that. The challenge is I needed the code to work for the consumers who passed in both the new interface and the old interface. And so the only thing that's documented is the new interface. It just takes a single parameter object. But what the code does on the downcast is then it secretly passes the second, third, fourth, and fifth parameters as well. And it secretly adds properties to the first parameter that's now the parameter object so that it had all of the properties of what was the previous first parameter as well. So anybody who is passing the old interface, the code has been changed so that it will still pass what effectively looks like the same information, especially with if you consider some duck typing on that first parameter because they'll have more than it used to have.
And for people who are passing the new interface where they just have a single parameter object, everything works great. If they want to inspect the function definition, they can tap into those other parameters, but they have no need to. That's just there for backwards compatibility purposes.
So that code had to be sprinkled. I couldn't centralize that code. I could centralize the transformation to an extent, but I had to call the downcast everywhere it was needed. There wasn't a single point in the request processing pipeline where I could do that. So it was a little bit harder to manage downcasting.
Thomas Betts: But that again, is your problem that you, as a maintainer, have to absorb versus having to figure out for your consumers, do this here and do that there and make all these little selective changes to the consumption of the API. You just accepted this isn't good for them. Does it make it easier for them to understand because you haven't added the complexity to the API surface?
Brandon Byars: Yes, and this one would've been awkward, for certain API consumers to embrace the change because it's not directly visible from the REST API contract. It's an embedded API inside the REST API contract. So I was particularly concerned about how to roll this change out in a way that was stable for consumers, didn't cause a lot of friction, or have them scratch their head and having to pour over documentation to understand the nature of the change. I want it to be as seamless as possible for them, while giving everybody who's adopting the API for the first time or getting started with it, what is a much cleaner interface.
Thomas Betts: I wanted to go back to… You mentioned the hidden interfaces was another landmine to worry about. Is it just a matter of you didn't provide documentation but you accept something? And is that from laziness or is it actually an intentional choice to say, "I'm not going to document this part of the API?"
Brandon Byars: Yes, it's intentional. I certainly have examples of laziness too. So I'm not trying to dismiss that as an approach, but in the cases that I wanted to at least call out, what happened was I got something wrong to begin with. And of course, when you get something wrong inside a code base, you just refactor it. But when you get something wrong in a way that is exposed to consumers, to which you don't control, it's a public API, it's harder to fix it. And this is generally where versioning kicks in that allows me a path to fix it. And then it's the consumer's problem to upgrade.
I had an example where I mentioned that one of the bits of functionality from Mountebank was shelling out to another program to transform something about the response from this virtual service. Originally, I had passed these parameters as command line arguments and it turns out that I just was not clever enough to figure out how to quote them for the shell escaping across all the different shells, primarily the Windows ones are where a lot of the complexity kicks in, especially the older cmd.exe is where you get a lot of complexity around shell quoting that isn't as portable to a lot of the posix shell based terminals.
So I got it wrong and I spent probably a full day trying to fix it. And I remember asking myself at one point, "Why am I doing this?" To just pass the arguments as environment variables problem solved. And eventually, I did that, and so I changed the interface of this programmable interface to pass in environment variables instead of command line parameters because I couldn't figure out how to pass in the command line variables the right way with the right shell escaping of quotes. And to try to strike a balance on stability and giving the new interface that I wanted, I wrote it in such a way that Mountebank was still passing the command line interfaces and if it didn't work because it broke something on a Windows shell around shell escaping, well, it never worked, so that's fine. And if it used to work for you, it should continue to work for you. Everybody else, just the new adopters just do the environment variables. They get a much more scalable solution.
But this is where those hidden mines that we talked about can trip you up because it turns out that escaping quotes on the shell wasn't the only problem. It turns out that shells also have a limit of how many characters you can pass to a command line program. And again, especially cmd.exe has the lowest limit. And so I had to end up truncating the amount of information passed in ways that actually could break previous consumers just to get over that limitation.
And it was a really interesting exercise to go through because I had to trade off what was the lesser of two evils. Should I cut a new version and force everybody to upgrade? When in fact, I had no evidence that anybody was tripping over this bug. If I truncated the number of characters into the shell, I had no evidence that was breaking anybody. And to this day, I don't have any evidence that it did. So I ended up making the change where I hid the previous interface. It's not on the documentation, it's still passed the command line parameters that shortened them in ways that could have broken somebody, that used to work in the past and no longer does.
And I left some notes in the release notes that get pushed out with every release of Mountebank, but I tried to make it instead of a pure architectural guarantee of correctness, I put on my product manager hat and say, "As a user, what's the lesser of two evils?" If I run into this bug, the path to resolution is pretty clear. Can I give them as much direction as possible if that's something they're running into in the document, the release notes and so forth? And can I do this in a way that hopefully impacts nobody, but if it does, in fact as few people as possible? And it felt like that was a path with less friction than releasing a new version that would've affected everybody in the upgrade path. But that was a really different way for me of thinking about API evolution, because I had to think about it more like a product manager than an architect.
Versioning is generally an architectural concern, but it's really part of your public interface that you release to users. It's also part of your product interface. And when you come at it with a product mentality and you think about how to minimize friction, you have a more nuanced understanding of the trade offs. And I certainly did in that case.
Thomas Betts: Yes, that got to where I wanted to wrap up with talking about how developers and architects should think about API evolution, not just from the programming problems that you have. And I like that last example. Actually, I wanted to go back to it because you had a bug and sometimes, when you have a coding bug, you're like, "Oh, I can solve this inside this function and no one will know anything about it." But sometimes, you realize the bug is only a bug because of what's being passed in as input. And the fix is you have to change the input and that in this case, changes the API. Tell me more about that product management thinking of saying, "Well, we haven't seen any evidence that our customers are using this and we think it'll be a minimal impact and it'll be an acceptable impact for them."
Brandon Byars: And there's a lot. This is where it's a judgment call. It always is anytime you're managing a product, but if you never risk upsetting some users with some feature changes as a product manager, then your product is going to be stuck in stasis. So you know have to evolve. But you also know that you want to introduce as little friction as possible because in your request for new users, you don't want to lose the users you already have. It's one of the difficult parts of product management. And so in this case, it felt like the way to walk that tight rope was to take into consideration a few facts. The feature under consideration had not been out in the wild for very long before the bug was reported. So it's not like it had seen wide adoption yet.
The first change, switching to environment variables happened pretty quick. So most people who had used it should be using the new interface. And the problem was some of those people were running into a bug because they passed large strings of text to the command line. They had no idea why this was breaking because it's just an environment variable. They don't understand that it's also passing this in the command line. That was more confusing to them than stripping that functionality out.
So I was breaking people using the new interface. I had no evidence that there was any adoption of the old interface because it had this bug. And so it was a risk/reward trade off that said, "Hey, this feels like the path of least friction for the most people that leads to the cleanest outcome, so let's go down that path." And I haven't regretted it in that instance, but it's certainly something that requires a lot of nuance.
Thomas Betts: I remember in your talk, you briefly mentioned that you are working on an article for this that'll be published, coming soon. Is that still in the works?
Brandon Byars: That is still in the works? So I had started an article last year and I put it on ice and this QCon talk that I gave in this podcast, Thomas, as a good nudge 'cause I'm hoping over the winter break to get that over the line. If I can, then I've had a first pass review with Martin Fowler who's posted some of my other work, and I'm hoping that we can get it on his blog in the new year.
Thomas Betts: All right. Well hopefully, people will be able to find that on… Is it martinfowler.com?
Brandon Byars: That's it. Yes. The one and only.
Thomas Betts: All right. Hopefully, that'll be coming out soon, early next year.
Brandon Byars: That's my hope. Yes.
Thomas Betts: Well, I want to thank you again, Brandon Byers for joining me on another episode of the InfoQ podcast.
Brandon Byars: Thank you so much, Thomas, for having me.
2022 Year in Review: ADRs, Staff Plus, Platforms, Sustainability, and Culture Design
InfoQ Software Architecture & Design Trends 2022
The InfoQ Podcast: .NET Trends Report 2022
Managing an API as a Product with Deepa Goyal
A round-up of last week’s content on InfoQ sent out every Tuesday. Join a community of over 250,000 senior developers. View an example
We protect your privacy.
You need to Register an InfoQ account or Login or login to post comments. But there’s so much more behind being registered.
Get the most out of the InfoQ experience.
Allowed html: a,b,br,blockquote,i,li,pre,u,ul,p
Allowed html: a,b,br,blockquote,i,li,pre,u,ul,p
Allowed html: a,b,br,blockquote,i,li,pre,u,ul,p
A round-up of last week’s content on InfoQ sent out every Tuesday. Join a community of over 250,000 senior developers. View an example
We protect your privacy.
Real-world technical talks. No product pitches.
Practical ideas to inspire you and your team.
March 27-29, 2023. Attend in-person or online.
QCon London brings together the world’s most innovative senior software engineers across multiple domains to share their real-world implementation of emerging trends and practices.
Level-up on 15 major software and leadership topics including Modern Frontend Development and Architecture, Enhancing Developer Productivity and Experience, Remote and Hybrid Work, Debugging Production, AI/ML Trends, Data Engineering Innovations, Architecture in 2025, and more.
SAVE YOUR SPOT NOW
InfoQ.com and all content copyright © 2006-2023 C4Media Inc.
Privacy Notice, Terms And Conditions, Cookie Policy
- Published in Uncategorized